From experiment
to everyday use
We build the platform around your models: the data they learn from, the checks each release has to pass and the monitoring that shows they’re still working after launch.
Thanks, we’ll be in touch soon.
{{ heroStatus }}
You’re in good company
A few of the companies we’ve worked with.
When a good pilot stalls
A model that works in a demo is a promising start. Running it every day takes more: the data it learns from, the checks it passes before each release and a way to know it’s still right. That work is often called MLOps. Without it, a pilot stays a pilot, or goes live and can slowly get worse without anyone noticing.
Two kinds of model, one discipline
Some models you train on your own data, to predict, classify or check an image. Others you build on: a language model from a provider, shaped by your prompts and the documents it can search. The work differs, but what production needs is the same.
Models you train
The work is in the data: collecting it, labelling it, keeping each version and retraining when the world it describes changes.
Models you build on
The work is in what surrounds the model: the prompts, the documents it searches and the checks on its answers, and testing again when the provider releases a new version.
Either way
Every version recorded, every change tested before release, every live model watched, and a quick way back.
Data your models can learn from
A model is only as dependable as the data underneath it. We build the platform that keeps that data in order, so every result can be traced back and every training run repeated.
Data with versions
Each training run records the exact data, code and settings it used, so it can be repeated and compared.
The same inputs, in training and live
Inputs are prepared once and used in both, so a model sees in production what it learned from.
A record of every model
One place (a model registry) lists each model and prompt: its version, how it was tested, where it runs and who owns it.
Tested before every release
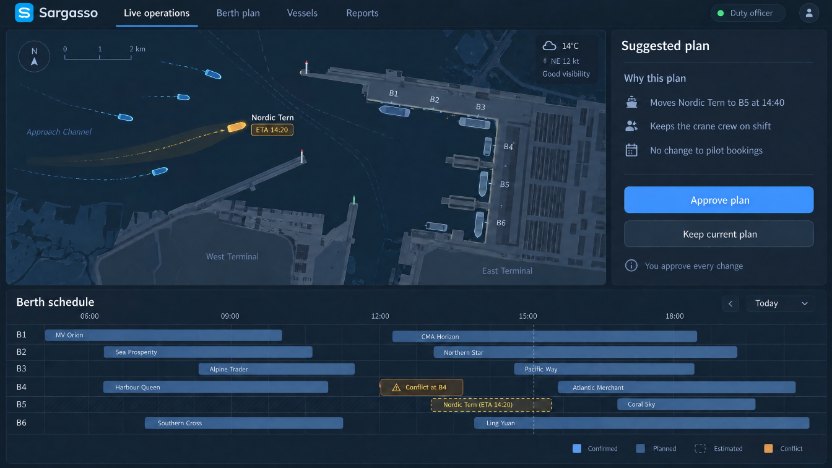
Every change is tested before it reaches anyone: a new model, a retrained one, a new prompt or a provider’s new version. Each is scored on a set of real cases, including the hard ones, and goes live only if it does at least as well where it matters. If it falls short on a case that matters, it waits for a person to decide.
How to test an AI feature before it launchesReleased safely, reversed quickly
A new version can run alongside the current one first, answering in the background so the two can be compared (shadow mode). Then it serves a small share of requests (a canary release), then everyone. If something looks wrong, you go back to the last good version, a step that’s tested before it’s needed.
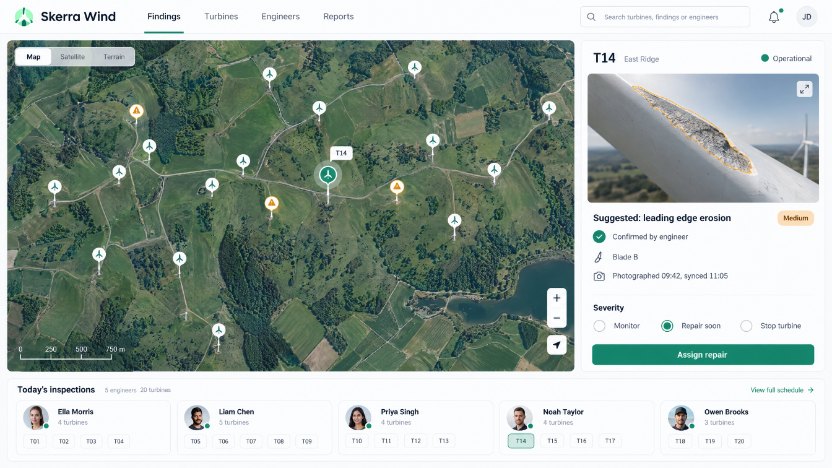
Watched once it’s live
Quality
Samples of real results reviewed by people, alongside feedback from the people using them.
Changing data
An alert when the inputs start to look different from what the model learned from.
Speed and cost
Response times and the cost of each request tracked, so neither grows unnoticed.
Uncertain cases
When the model isn’t sure, the case goes to a person, and their decision helps improve the next version.
Every live model is watched on what matters to your business, and each check has an owner who hears about a problem first.
Kept accurate as things change
Your business changes, and so does the data your models learn from. Providers release new models and retire older ones. We plan for both: retraining when the evidence calls for it, and testing a replacement on your own cases before anything switches.
Then we keep running the platform with you, or hand it over with the code, the test cases, the record of every model and the documentation.
Work with us as a dedicated team, on a fixed price project or a mix of both.
Compare engagement modelsLet’s ship it better
Tell us what the model needs to do, where it runs today and what has to be true before you can rely on it. We’ll talk through the options and a sensible first step.
Thanks, we’ll be in touch soon.
{{ ctaStatus }}